Openlayer’s Blog
No commitments, unsubscribe any time.
September 23, 2026AI evals
Introducing jevals: typed decisions for agent evals and guardrails
An open-source Python library for evaluating agent behavior and turning the same checks into runtime guardrails using typed decision models.
LLM Coding Benchmarks: The Complete Guide (Updated)
September 17, 2026Testing
AI Incident Response for Model Failures
September 17, 2026AI agents
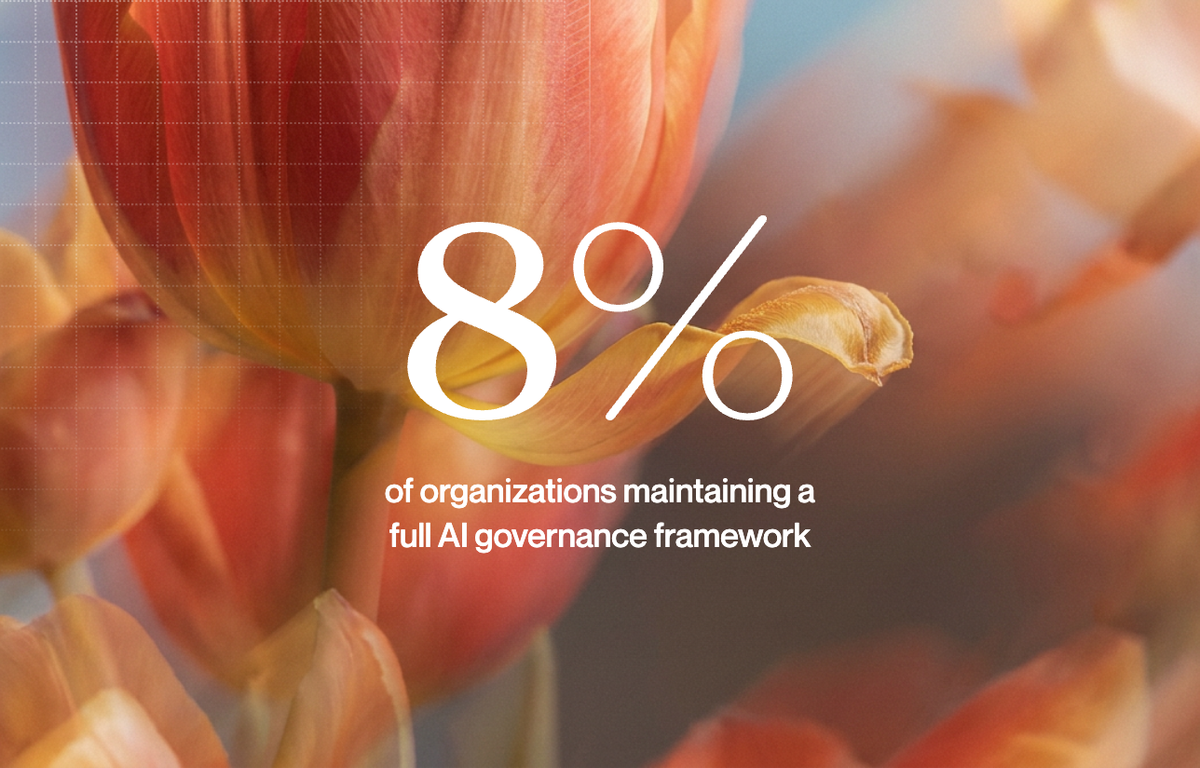
Continuous AI Risk Monitoring: Beyond Snapshots
September 17, 2026Governance
How to Red-Team AI Models Effectively
September 17, 2026AI evals
Tiering AI Systems: Internal Risk Classification
September 8, 2026Governance
AI Risk Assessment Report for Auditors
September 8, 2026AI evals
September 17, 2026
LLM Coding Benchmarks: The Complete Guide (Updated)
September 17, 2026
AI Incident Response for Model Failures
September 17, 2026
Continuous AI Risk Monitoring: Beyond Snapshots
September 17, 2026
How to Red-Team AI Models Effectively
September 8, 2026
Tiering AI Systems: Internal Risk Classification
September 8, 2026
AI Risk Assessment Report for Auditors
July 28, 2026
NAIC AI Model Bulletin: What Insurers Must Prepare for
July 21, 2026
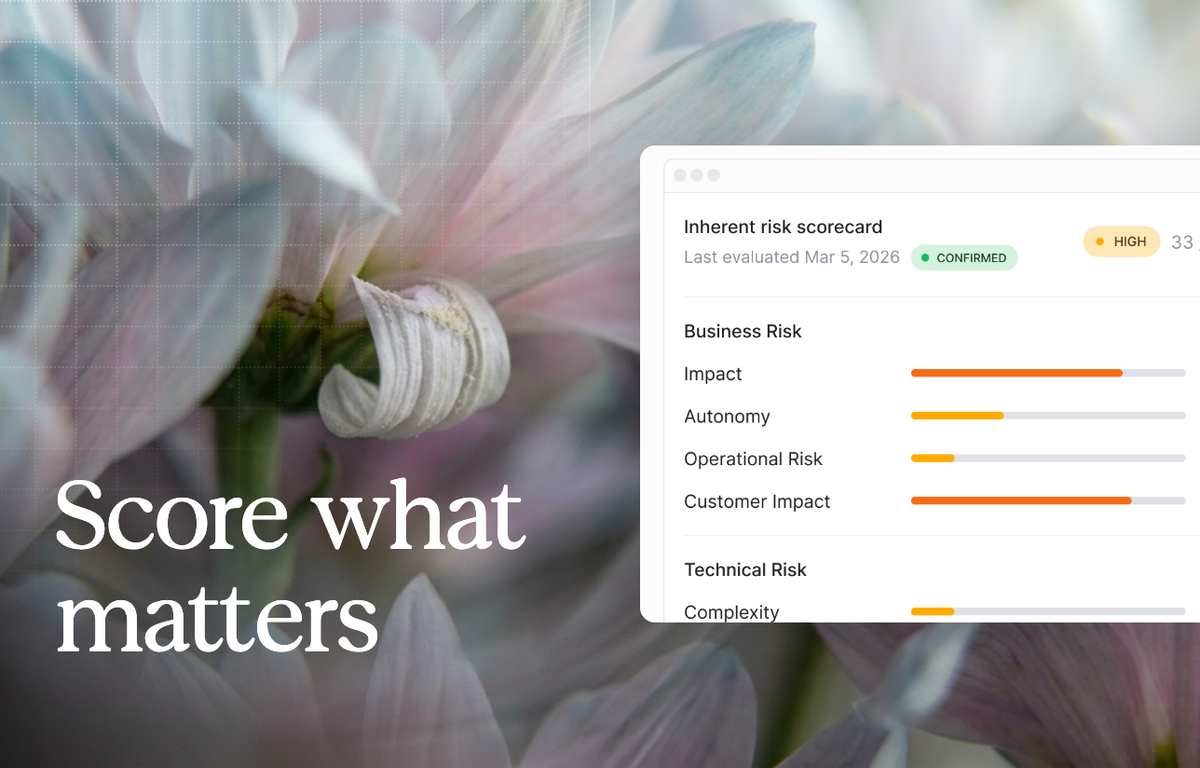
Quantify and Prioritize AI System Risk with Scoring
July 13, 2026
PII Detection in LLM Outputs: AI Team Guide
July 13, 2026
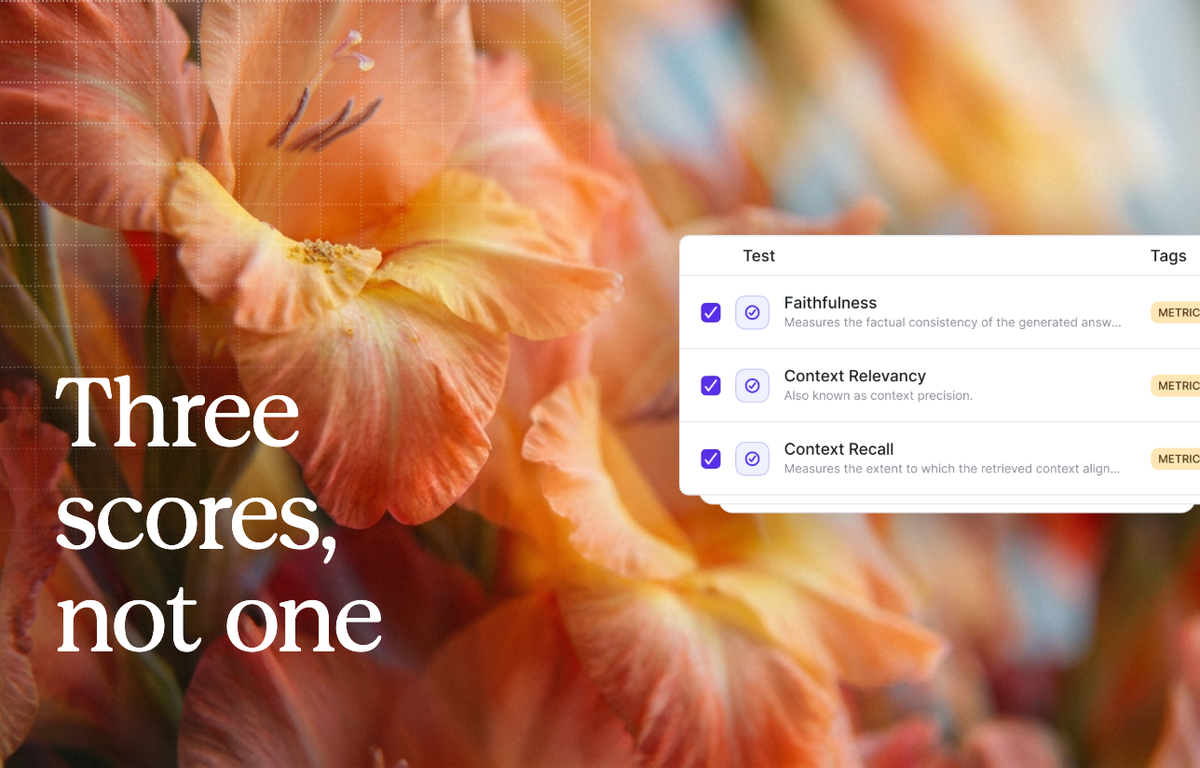
RAG Evaluation in Production: Groundedness, Faithfulness, and Retrieval Quality
June 2, 2026
OpenAI evals: A complete guide to evaluation frameworks
March 30, 2026
LLM-as-judge: A complete guide to evaluation best practices
March 30, 2026
Model monitoring in 2026: A complete guide for ML teams
March 27, 2026
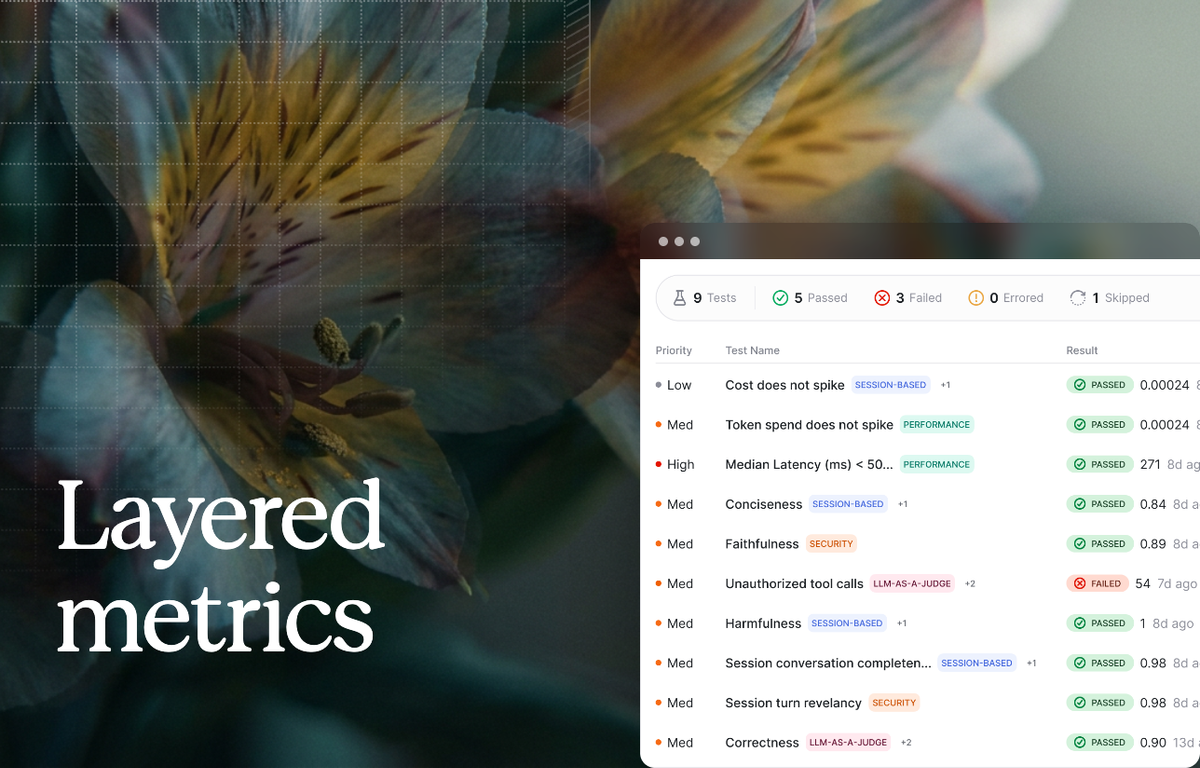
LLM evaluation metrics: Complete guide
March 9, 2026
Agent evaluation: Complete guide to testing AI agents
February 11, 2026
RAG Groundedness Evaluation Guide
January 29, 2026
Needle in a Haystack: AI Testing Guide
January 2, 2026
Galileo reviews, pricing, and alternatives
December 22, 2025
Best AI drift detection tools for production models
December 22, 2025